
- Status
- Verified
- Base model
- …
- Lineage
- …
- Unchanged from base
- …
- Trending
- #37
- Downloads, 30 days
- 55.9k
- Weights
- 782 GB
- Revision
✒️ TechnicalReport | 📖 Documentation | 🤗 Hugging Face | 🤖 ModelScope
At a glance
- Parameters
- 223B
- Architecture
- Hy V4 Flash
- Context
- 1M tokens
- Format
- GGUF
- Languages
- zh, en
- Base model
- Quantized from tencent/Hy4-flash
- Released
- Nov 2026
- Updated
- Nov 2026
- Likes
- 79
- Downloads, all time
- 55,872
Run it
Pinned to the indexed revision.
llama-server -hf AngelSlim/Hy4-flash-GGUFThrough the hub: the same tools, each file from a source that is up (Hugging Face, ModelScope, IPFS), at this revision. The last line checks every file against the hash the tree names.
export HF_ENDPOINT=https://gethologram.ai
hf download AngelSlim/Hy4-flash-GGUF --quiet && hf cache verify AngelSlim/Hy4-flash-GGUF
Papers
Read the full model card
中文 | English
AngelSlim
A more accessible, comprehensive, and efficient toolkit for large model compression.
✒️ TechnicalReport | 📖 Documentation | 🤗 Hugging Face | 🤖 ModelScope
Hy4-flash GGUF
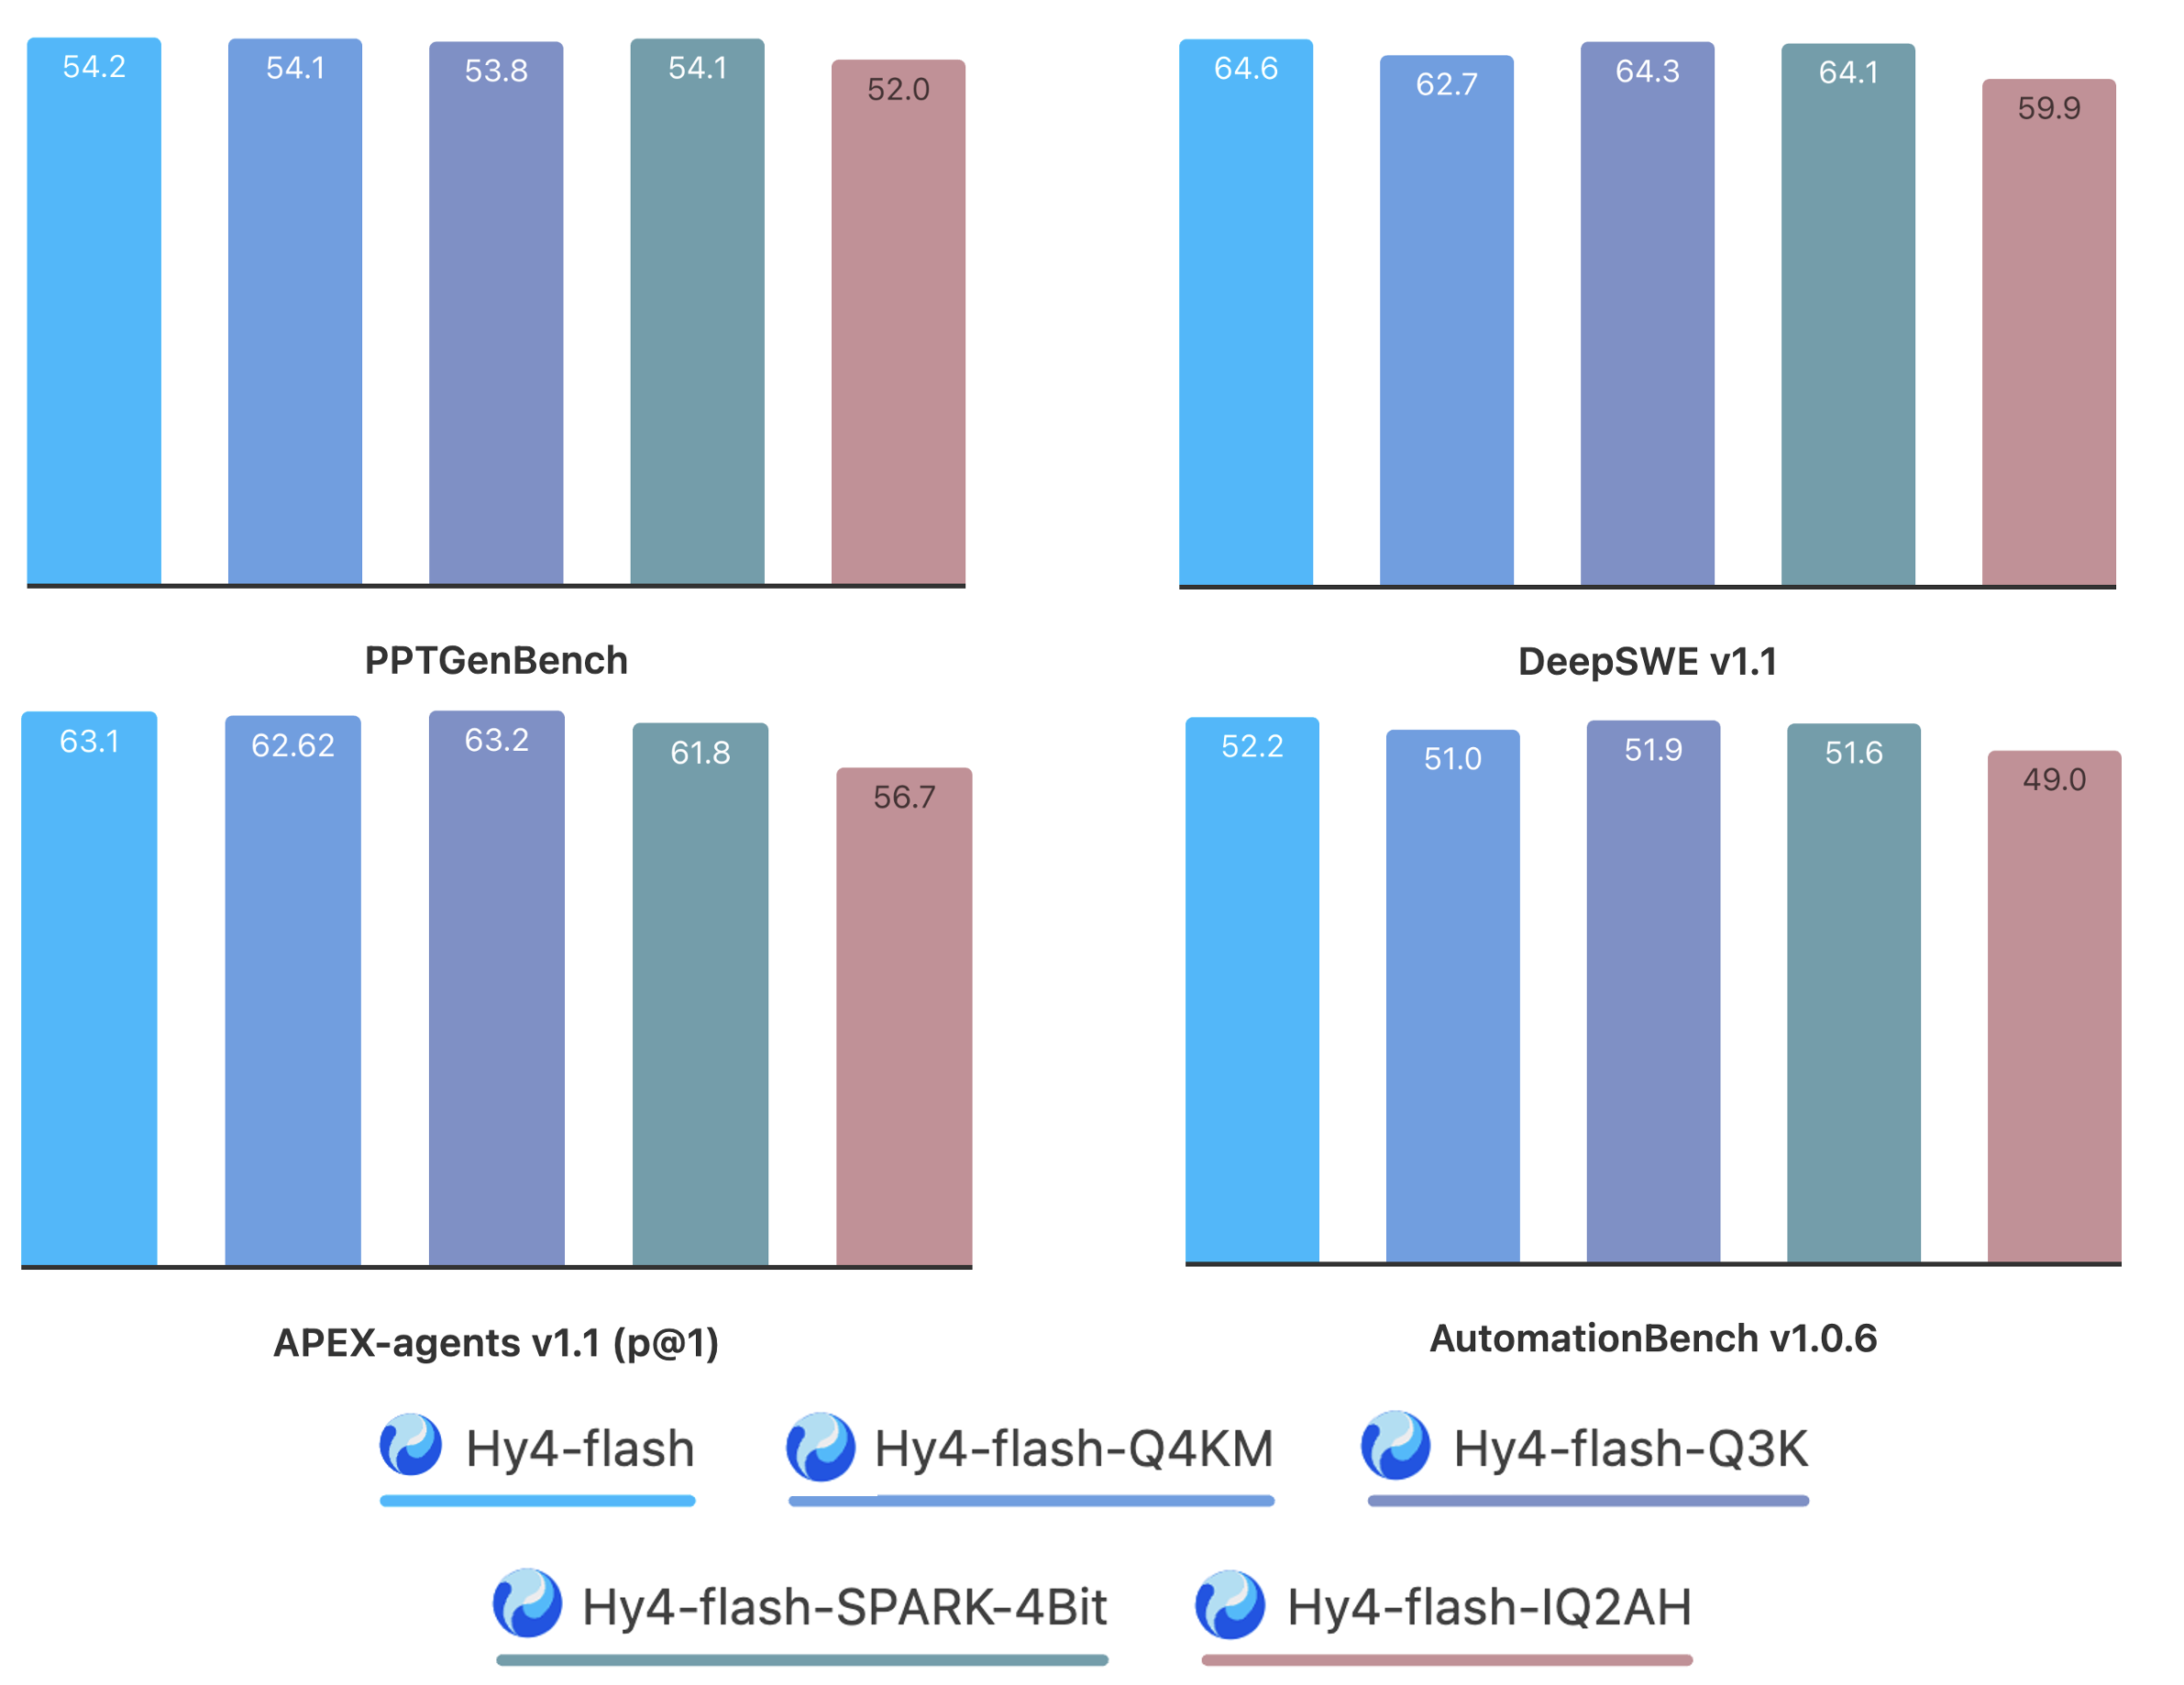
Five GGUF builds of Hy4-flash: tencent/Hy4-flash
| file | model size | bpw (overall) | bpw (excl. Engram table) |
|---|---|---|---|
Hy4-flash-Q4_K_M.gguf |
156.79 GiB | 6.05 | 5.27 |
Hy4-flash-SPARK-4Bit.gguf |
151.3 GiB | 5.84 | 4.78 |
Hy4-flash-SPARK-4Bit-Fast.gguf |
148.6 GiB | 5.74 | 4.63 |
Hy4-flash-Q3_K.gguf |
144.70 GiB | 5.58 | 4.62 |
Hy4-flash-IQ2-AH.gguf |
125.73 GiB | 4.85 | 3.60 |

1. What these are
Hy4-flash-Q4_K_M.gguf — standard 4-bit, the safe default. The routed experts follow llama.cpp's
Q4_K_M recipe: gate/up are Q4_K, and down gets Q6_K on 19 layers via llama.cpp's fixed rule and
Q4_K on the other 22. Most non-expert weights are Q8_0. Use this unless you are memory-constrained.
Hy4-flash-SPARK-4Bit.gguf — the SPARK-4Bit build (NVIDIA's 4-bit floating-point format). Suited for Spark devices.
Hy4-flash-SPARK-4Bit-Fast.gguf — a variant of the SPARK-4Bit build, 2.7 GiB smaller. Also suited for Spark devices.
Hy4-flash-Q3_K.gguf — mixed Q3_K/Q4_K experts. The routed-expert gate/up projections keep
Q4_K on 19 layers chosen by quantization sensitivity and drop to Q3_K on the other 22; down is Q4_K.
Everything outside the routed experts is the same as Q4_K_M.
Hy4-flash-IQ2-AH.gguf — the smallest of the five. The routed-expert gate/up projections run
at 2.0625 bpw (IQ2_XXS) and down at Q4_K, while most non-expert weights stay in BF16 rather than Q8_0.
Strata version coming soon
2. SPEED
The test was conducted in real workbuddy scenarios and cases.
Mac M5 Max 128GB
| format | Prefill tok/s (4K / 16K / 32K) | Decode tok/s (4K / 16K / 32K) |
|---|---|---|
| Q4_K_M | 629.8 / 448.1 / 418.6 | 48.13 / 45.18 / 44.15 |
| Q3_K | 743.2 / 563.0 / 520.6 | 50.34 / 49.47 / 47.37 |
For code generation, Q3_K reaches up to 70 tok/s.
RTX Spark 128GB
| format | Prefill tok/s (4K / 16K / 32K) | Decode tok/s (4K / 16K / 32K) |
|---|---|---|
| SPARK-4Bit-Fast | 799 / 717 / 707 | 31.95 / 33.14 / 33.39 |
| SPARK-4Bit | 765 / 686 / 666 | 25.80 / 28.16 / 30.3 |
For code generation, SPARK-4Bit-Fast reaches up to 40 tok/s.
3. How to use
General Usage
The support is in PR #32517 and not merged yet, so check out the PR branch:
git clone https://github.com/ggml-org/llama.cpp
cd llama.cpp
git fetch origin pull/32517/head:hy4-flash
git checkout hy4-flash
Build:
cmake -B build                # add -DGGML_CUDA=ON for NVIDIA GPUs; Metal is on by default on macOS
cmake --build build --config Release -j
Chat in the terminal:
./build/bin/llama-cli -m Hy4-flash-Q4_K_M-00001-of-00002.gguf -c 8192 -ngl 99 --jinja
OpenAI-compatible server (http://localhost:8080):
./build/bin/llama-server -m Hy4-flash-Q4_K_M-00001-of-00002.gguf -c 8192 -ngl 99 --jinja --port 8080
Image input, with the mmproj file:
./build/bin/llama-mtmd-cli -m Hy4-flash-Q4_K_M-00001-of-00002.gguf --mmproj mmproj-Hy4-flash-bf16.gguf \
    --image photo.png -p "Describe this image." -c 8192 -ngl 99 --jinja
Mac M5 Max 128GB
cd llama.cpp
git checkout 2cbca389f
git apply hy4-flash-mac-minimal.patch
cmake -B build -DCMAKE_BUILD_TYPE=Release -DGGML_METAL=ON && cmake --build build -j
RTX Spark 128GB
Derived on Nov 19, 2026 from Hugging Face at revision 65acb8ae, README.md .
17 files, 782 GB. Every download is checked against its address.